
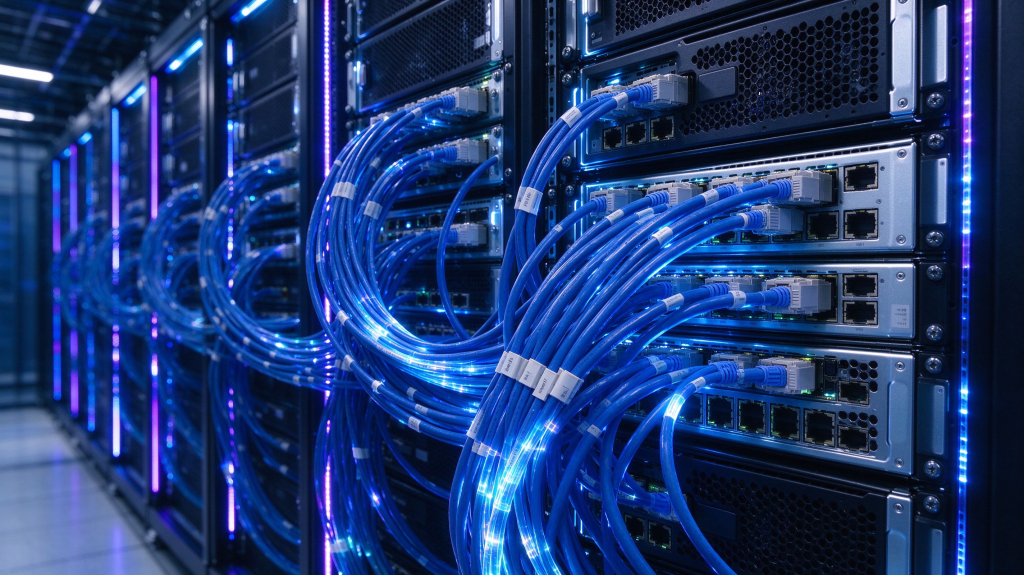
Short answer: To estimate fiber needs for an AI rack, count from the GPU up: multiply GPU count by fabric links per GPU, then by fibers per link (8 fibers per 400G link, 16 per 800G DR8). A single NVIDIA NVL72 rack with 72 GPUs at 400G needs about 576 fiber strands for compute fabric alone; at 800G DR8 that rises to 1,152 strands. After adding storage fabric, management network, and spine uplinks, plan for 1,200+ strands per rack, and 10 to 20 times that at the aggregation layer.
Why AI Rack Fiber Math Is Different
Traditional data center design counted fiber per server — two 10G links, maybe four. AI rack design breaks that model. The relevant unit is no longer the server; it is the GPU and the network fabric each GPU needs to participate in training or inference at scale. When GPU density meets optical reality, the fiber count in a single rack can exceed what an entire data center floor used in 2010.
To put this in context: a typical data center floor in 2010 ran roughly 1,000 to 2,000 fiber strands total. An AI rack can now hold that same count inside one rack, and the spine aggregation layer can carry 10 to 20 times that number. This changes how we plan patch panels, trunk cables, connector density, and even airflow.
Step-by-Step: Calculate Fiber Strands for an AI Rack
- Start with the GPU count in the rack. For an NVIDIA NVL72 deployment, that is 72 GPUs.
- Multiply by the fabric links per GPU. At 400G, each GPU needs one compute fabric connection, which translates to 8 fiber strands (4 transmit, 4 receive). 72 GPUs × 8 fibers = 576 strands for compute fabric alone.
- Move to 800G DR8 — 8 lanes of 100G — and each GPU needs 16 fibers. That becomes 1,152 strands, still for compute fabric only.
- Add storage fabric (NVMe-oF), management network, and inter-rack spine uplinks. The total passes 1,200 strands before redundancy or spine aggregation is even considered.
- When racks converge on a spine plane, multiply further. Eight NVL72 racks feeding a single spine plane means managing over 10,000 fiber strands at the aggregation layer; dual spine redundancy doubles that.
| Configuration | Unit | Fibers per unit | Rack total |
|---|---|---|---|
| 400G compute fabric (NVL72) | 72 GPUs | 8 strands per GPU | 576 strands |
| 800G DR8 compute fabric (NVL72) | 72 GPUs | 16 strands per GPU | 1,152 strands |
| + Storage, management, spine uplinks | 1 rack | — | 1,200+ strands |
| Aggregation layer (8 racks → 1 spine) | 8 racks | — | 10,000+ strands |
For more on the connector families that carry these counts, see our MPO vs MTP complete guide to high-density fiber optic connectors.
Why Connector Choice Becomes a Cooling Decision
At high strand counts, the patch panel becomes the architecture. The connectors, trunk cables, bend radius, and airflow gap determine whether a high-wattage GPU rack can actually breathe. The conversation shifts from “which connector has the lowest insertion loss” to “which connector lets me keep the rack cool.”
Consider the airflow math: a 1RU panel with 1,152 fibers using traditional MPO-24 trunks means 48 cables at roughly 3.0 mm outer diameter each — about 144 mm of cable cross-section in a 44.45 mm tall panel space. The cables do not just consume port density; they block the perforated panels and air passages that AI racks desperately need.
MMC and other VSFF (Very Small Form Factor) connectors change that equation. With higher fiber counts per connector and reduced-diameter fanout cables, total cable cross-section can be cut by roughly two-thirds. The fibers do not disappear — they stop acting like a wall in front of the intake. Learn more in our VSFF connectivity density and scalability guide and the LC to MMC port density article.
Match Trunk Base to Lane Count
Base architecture alignment is a layer of the fiber math that is easy to miss. For years, Base-12 dominated data center trunks and worked beautifully for 10G and 40G optics. But 800G and 1.6T optics use 8-lane or 16-lane configurations. Drop a Base-12 trunk into an 8-lane environment, and 33% of the fibers go dark — paid for, patched, and unused.
| Trunk base | Best match | Typical use |
|---|---|---|
| Base-8 | 400G/800G DR (8-lane) | Current AI and data center links |
| Base-12 | 10G/40G legacy, 12-lane systems | Legacy and mixed environments |
| Base-16 | Higher lane-count 1.6T implementations | Emerging high-density trunks |
| Base-24 | Grouped 8-lane links | High-density trunk applications |
The point is not to predict which base wins; the point is that trunk architecture must match lane architecture, or the deployment buys stranded capacity by design. Correct polarity and connector selection protect the investment, as explained in our fiber polarity guide.
Single-Mode Is the AI Default
Field deployments are converging on single-mode (OS2) fiber for AI-scale interconnects, even for intra-rack and intra-row distances that historically defaulted to multimode. At 800G and beyond, the power budget, reach requirements, and transceiver ecosystem increasingly favor single-mode, and silicon photonics-based transceivers are inherently single-mode devices. Multimode (OM4/OM5) still has a role in short-reach legacy environments and specific cost-sensitive deployments, but a rack designed for a 3-to-5-year lifespan should default to single-mode. See our OS2 single-mode patch cord product page for the assembly options.
CPO Does Not Remove the Fiber
Co-packaged optics (CPO) moves optics closer to the switch ASIC to reduce power and front-panel pluggable count. What often gets lost in the CPO conversation is that external fiber connectivity does not go away — it changes location, from the front panel to the mid-board or backplane. The fiber count, connector density, and cable management challenges remain, and CPO may even increase short-reach fiber connections inside the rack. For rack designers making decisions today, CPO is a horizon consideration, not a replacement for the fiber math that must be solved now. Our optical interconnect adoption and CPO reality article covers the deployment trade-offs in detail.
Practical Checklist for AI Rack Fiber Planning
- Count from the GPU up, not the server down — start with GPU count, fabric links per GPU, fibers per link, then add storage, management, and spine aggregation.
- Treat connector density as a thermal variable — every millimeter of cable diameter matters at 15 kW+ per rack; reduced-diameter fanout cables and higher-density connectors are thermal survival tools.
- Match trunk base to lane count — Base-8 or Base-16 aligns with 400G/800G/1.6T lane structures; a wrong base choice is a structural inefficiency that compounds at scale.
- Default to single-mode OS2 for new AI racks, and keep polarity and connector standards consistent end to end.
For high-density patching hardware designed around these constraints, review the high-density MMC fiber cassette and our AI data center MPO fiber solutions overview.
Frequently Asked Questions
How many fiber strands does a single AI rack need?
An NVIDIA NVL72 rack at 400G needs about 576 strands for compute fabric alone; at 800G DR8 that becomes 1,152 strands. After storage, management, and spine uplinks, plan for 1,200+ strands per rack.
Why does connector choice affect cooling in AI racks?
High fiber counts mean thick cable bundles in 1RU panels. Traditional MPO trunks can block perforated panels and air passages; MMC and other VSFF connectors cut cable cross-section by roughly two-thirds, restoring airflow to high-wattage racks.
What is the difference between Base-8, Base-12, and Base-16 trunks?
Base numbers refer to fiber groups in a trunk. Base-8 aligns with 400G/800G 8-lane optics, Base-12 suits legacy 10G/40G and 12-lane systems, and Base-16 targets higher lane-count 1.6T implementations. Using Base-12 with 8-lane optics leaves 33% of fibers dark.
Should AI racks use single-mode or multimode fiber?
Single-mode OS2 is the safer default for new AI racks because 800G+ silicon photonics transceivers are single-mode devices and the power budget and reach favor OS2. Multimode remains viable for short-reach legacy and cost-sensitive cases.